> ## Documentation Index
> Fetch the complete documentation index at: https://benchgen.com/docs/llms.txt
> Use this file to discover all available pages before exploring further.
# Train a model on benchmark results
> The skill that plans and launches fine-tuning, reinforcement learning and distillation, follows the job, and exports a merged model.
| The skill | `training-launch` |
| - | - |
| **Changes anything** | Yes. Training holds a GPU and spends credits, so it always plans first. |
| **It picks this up when you say** | "fine-tune this model", "train on what it got wrong", "distill it into a smaller model", "how is my training job", "merge the adapter" |
| **It hands over to** | `benchmark-launch` to measure whether the training actually helped |
## What it can do
* Plan and launch a LoRA fine-tune
* Plan and launch reinforcement learning with GRPO
* Continue training an existing adapter
* Train straight from a benchmark run
* Show what a job would submit before anything starts
* Report a job's status and tail its logs
* Show the dataset a finished run produced
* Merge a trained adapter and publish it as standalone weights
* Tell you which GPUs are free
Training from a run uses the dataset that run produced:
| Mode | What it trains on |
| - | - |
| `failures` | The questions the model got wrong, with the correct answers. The default. |
| `all` | Every question and answer. |
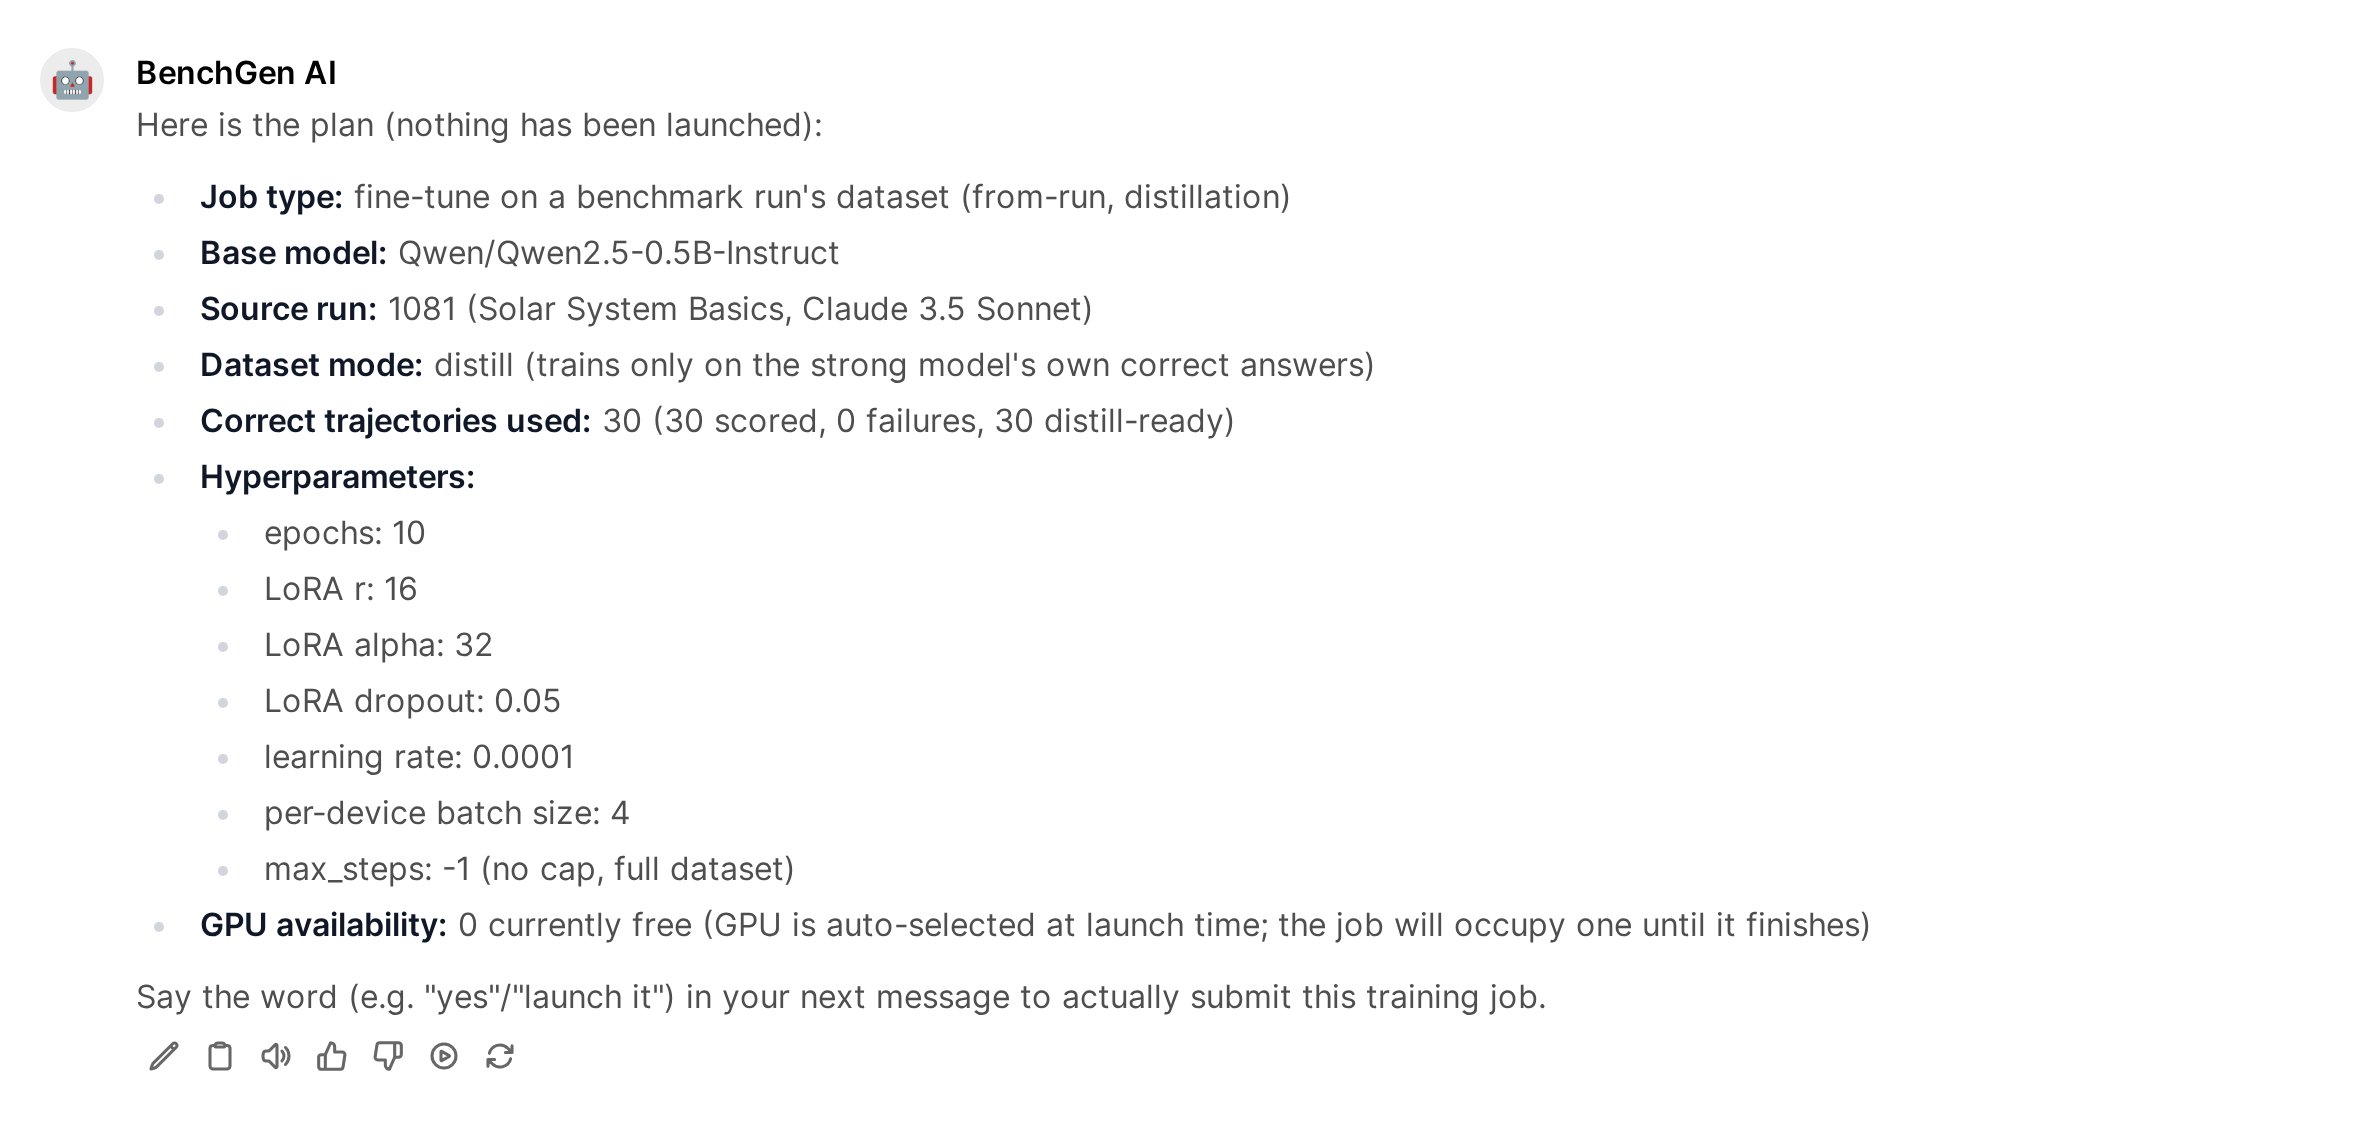
| `distill` | The questions a **strong** model got right, with its own reasoning. |
 ## Prompts to try
```text theme={null}
Plan a LoRA fine-tune of Qwen/Qwen2.5-0.5B-Instruct on yahma/alpaca-cleaned, 1 epoch,
50 steps maximum.
```
```text theme={null}
Plan a training from run so the model learns from the questions it got wrong.
```
```text theme={null}
Plan a distillation from run , dataset mode distill, base model Qwen/Qwen2.5-0.5B-Instruct.
```
```text theme={null}
What GPUs are free right now? How is job doing?
```
## What it will not do
* Start a job without a plan and a confirmation. Anything other than a yes cancels
* Run the whole loop unattended. Each step is confirmed on its own
* Stop or delete a training job. Do that from the web app
* Decide for you whether the model is the problem
The base model is a Hugging Face repository id such as `Qwen/Qwen2.5-0.5B-Instruct`, not a
catalogue display name. Check the `base_model` line in the plan before confirming.
If the misses came from a broken answer key, [fix the benchmark](/docs/skills/edit-a-benchmark)
first. Training against a wrong key teaches the wrong answer.
## Related
Measure, train, measure again, including distillation with real numbers.
Decide whether the misses are the model's fault first.
The same training from the web app.
Start jobs from your own code.