

What it can do
- Plan and launch a LoRA fine-tune
- Plan and launch reinforcement learning with GRPO
- Continue training an existing adapter
- Train straight from a benchmark run
- Show what a job would submit before anything starts
- Report a job’s status and tail its logs
- Show the dataset a finished run produced
- Merge a trained adapter and publish it as standalone weights
- Tell you which GPUs are free
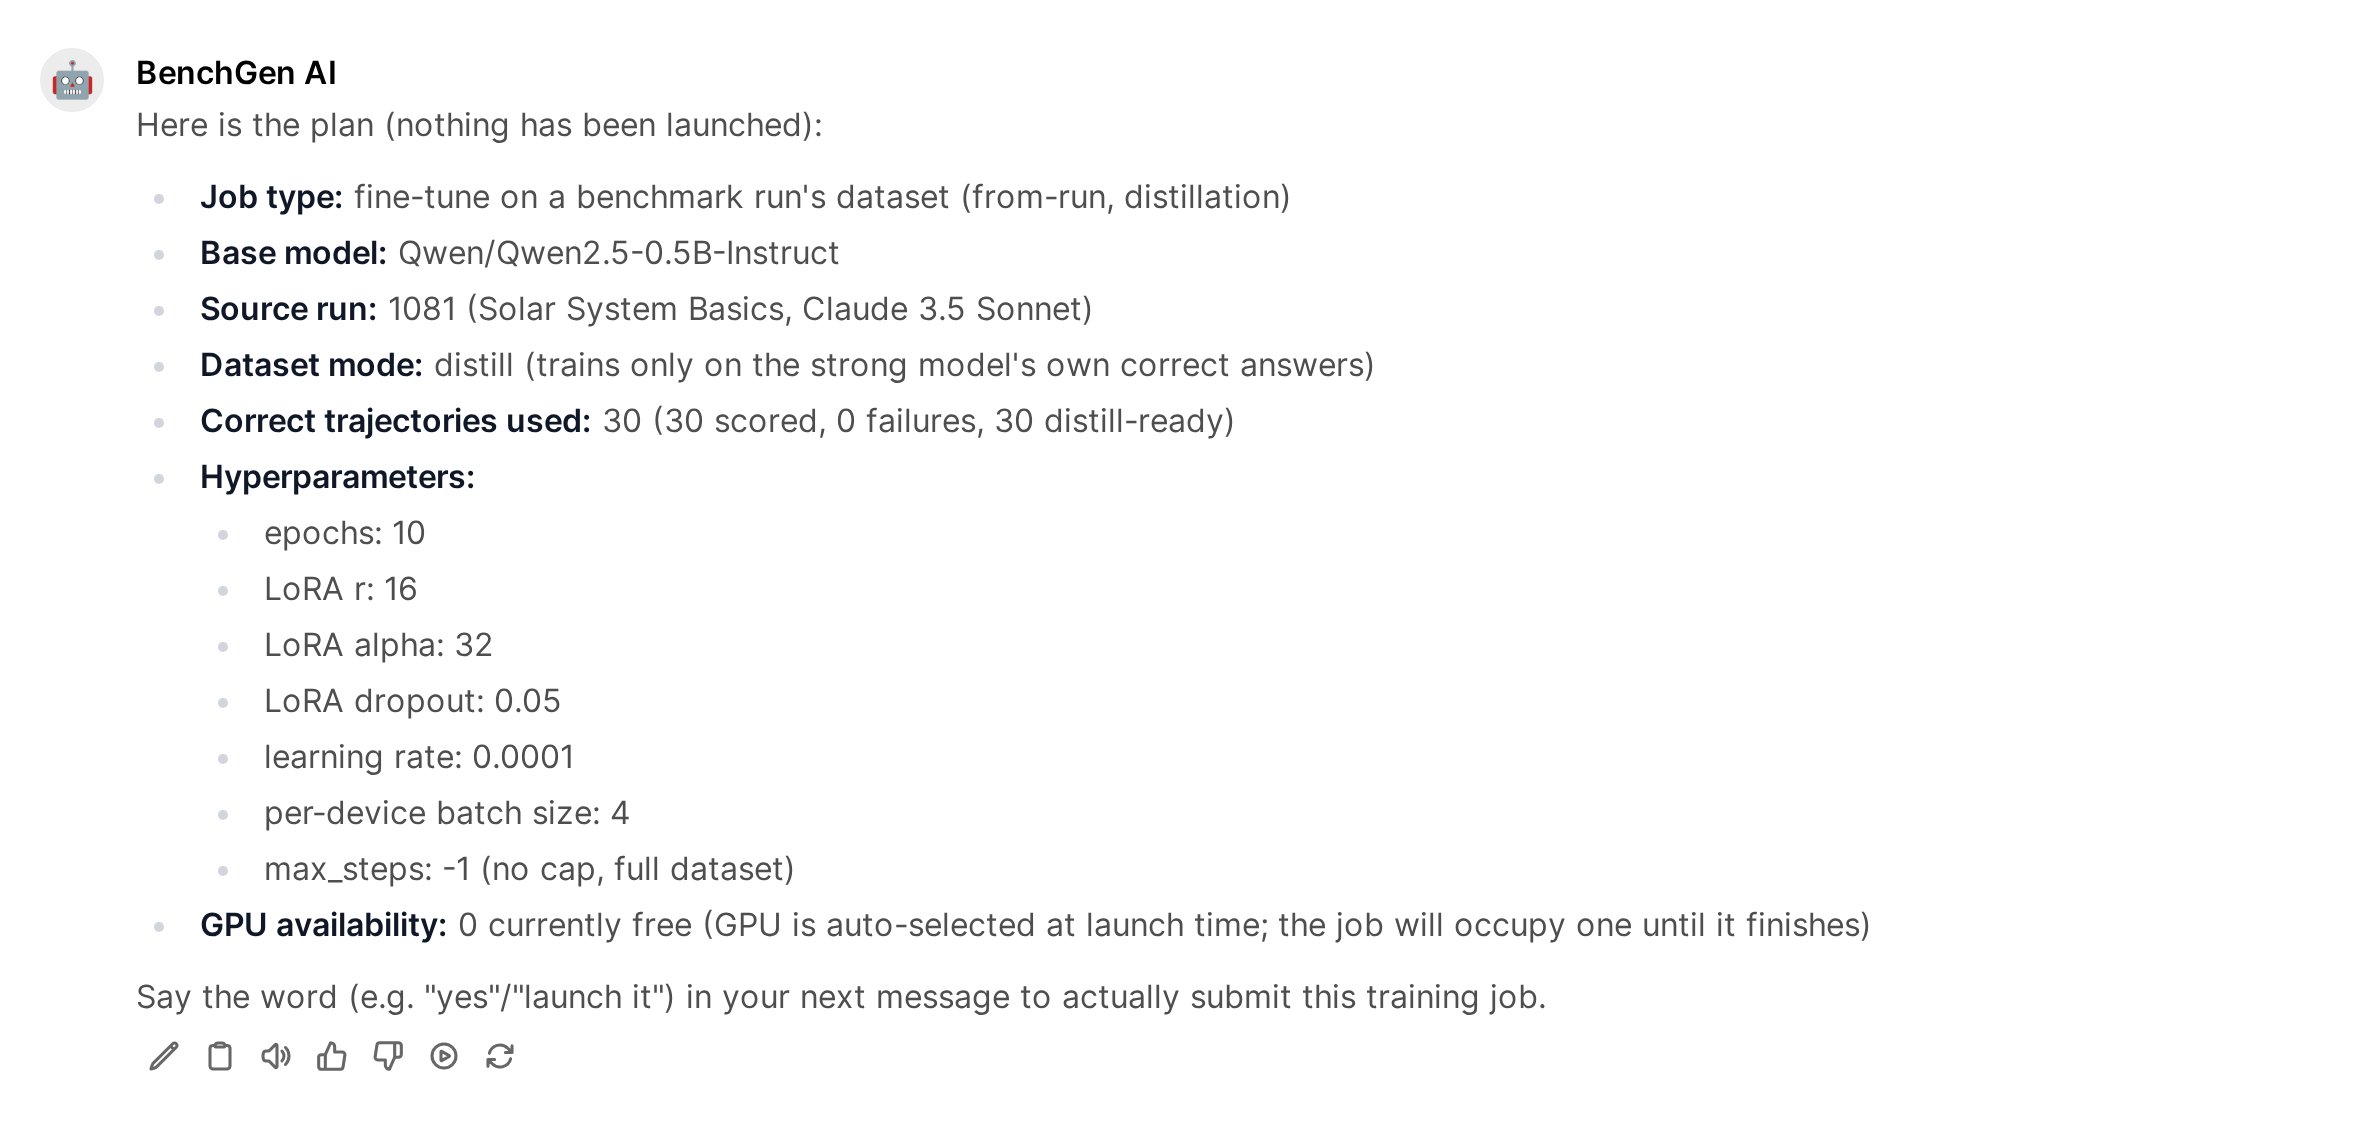
A training plan: what would be submitted, and nothing launched until you confirm
Prompts to try
What it will not do
- Start a job without a plan and a confirmation. Anything other than a yes cancels
- Run the whole loop unattended. Each step is confirmed on its own
- Stop or delete a training job. Do that from the web app
- Decide for you whether the model is the problem
If the misses came from a broken answer key, fix the benchmark
first. Training against a wrong key teaches the wrong answer.
Related
The full improvement loop
Measure, train, measure again, including distillation with real numbers.
Analyze the results
Decide whether the misses are the model’s fault first.
Fine-tune a model
The same training from the web app.
Launch training (API)
Start jobs from your own code.