

Prerequisites
- A saved model from a training run (see Merge & save a model), or any model in your workspace (see Add a model).
- A GPU node with free capacity.
Steps
1. Open the model and click Run Inference
Open the model’s card and click Run Inference in the top right.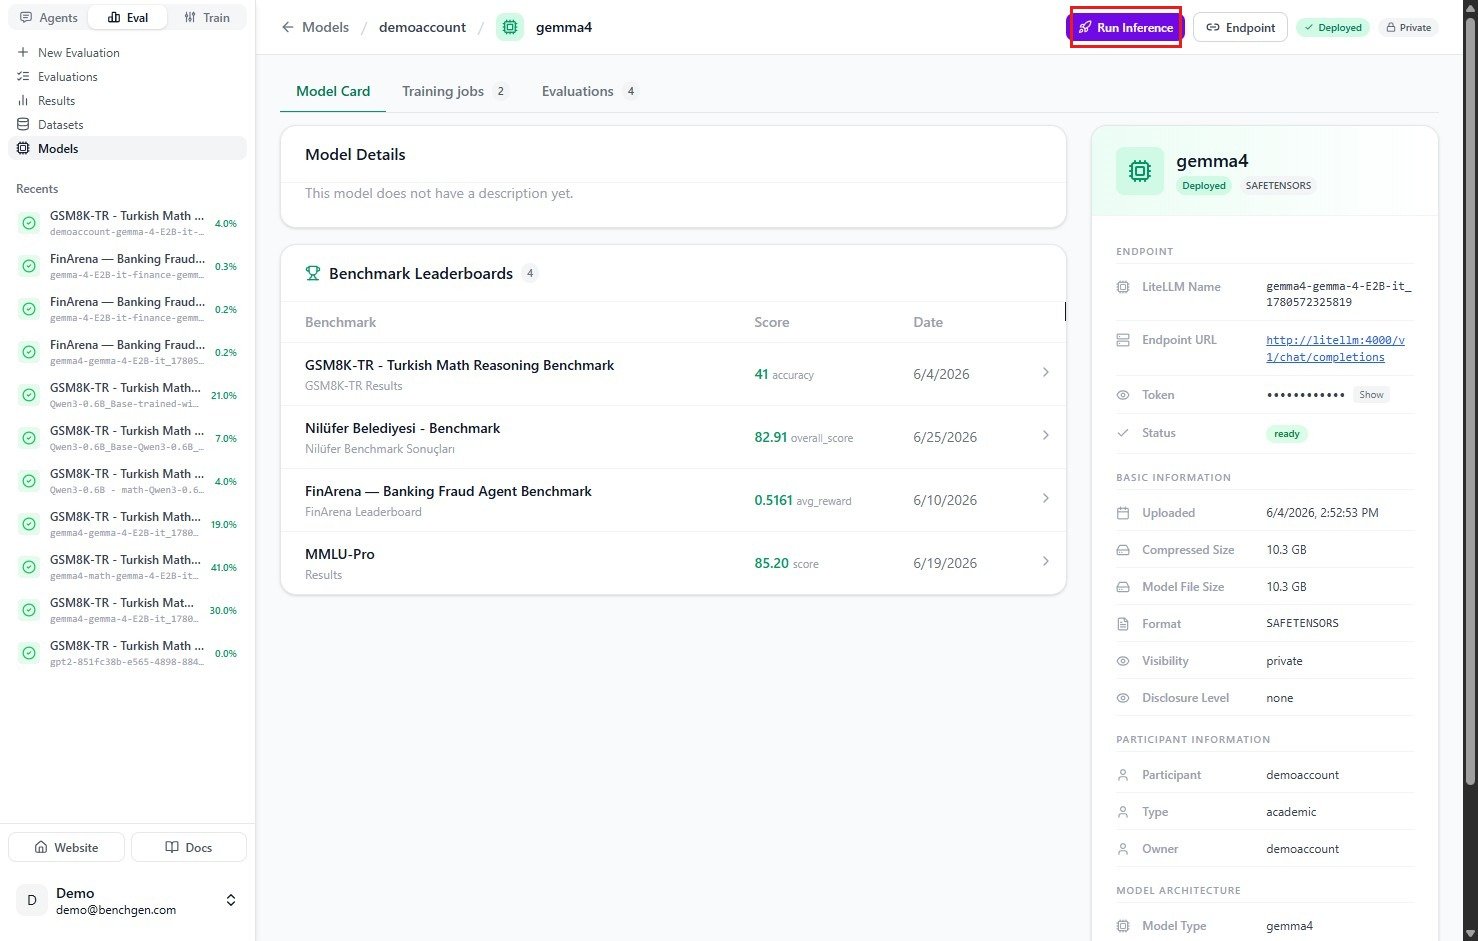
A model card with the Run Inference button outlined in the top right
2. Configure and start
In the Run Inference dialog, pick a GPU and review the inference settings (max tokens, temperature, top P, context length, precision), then click Run model.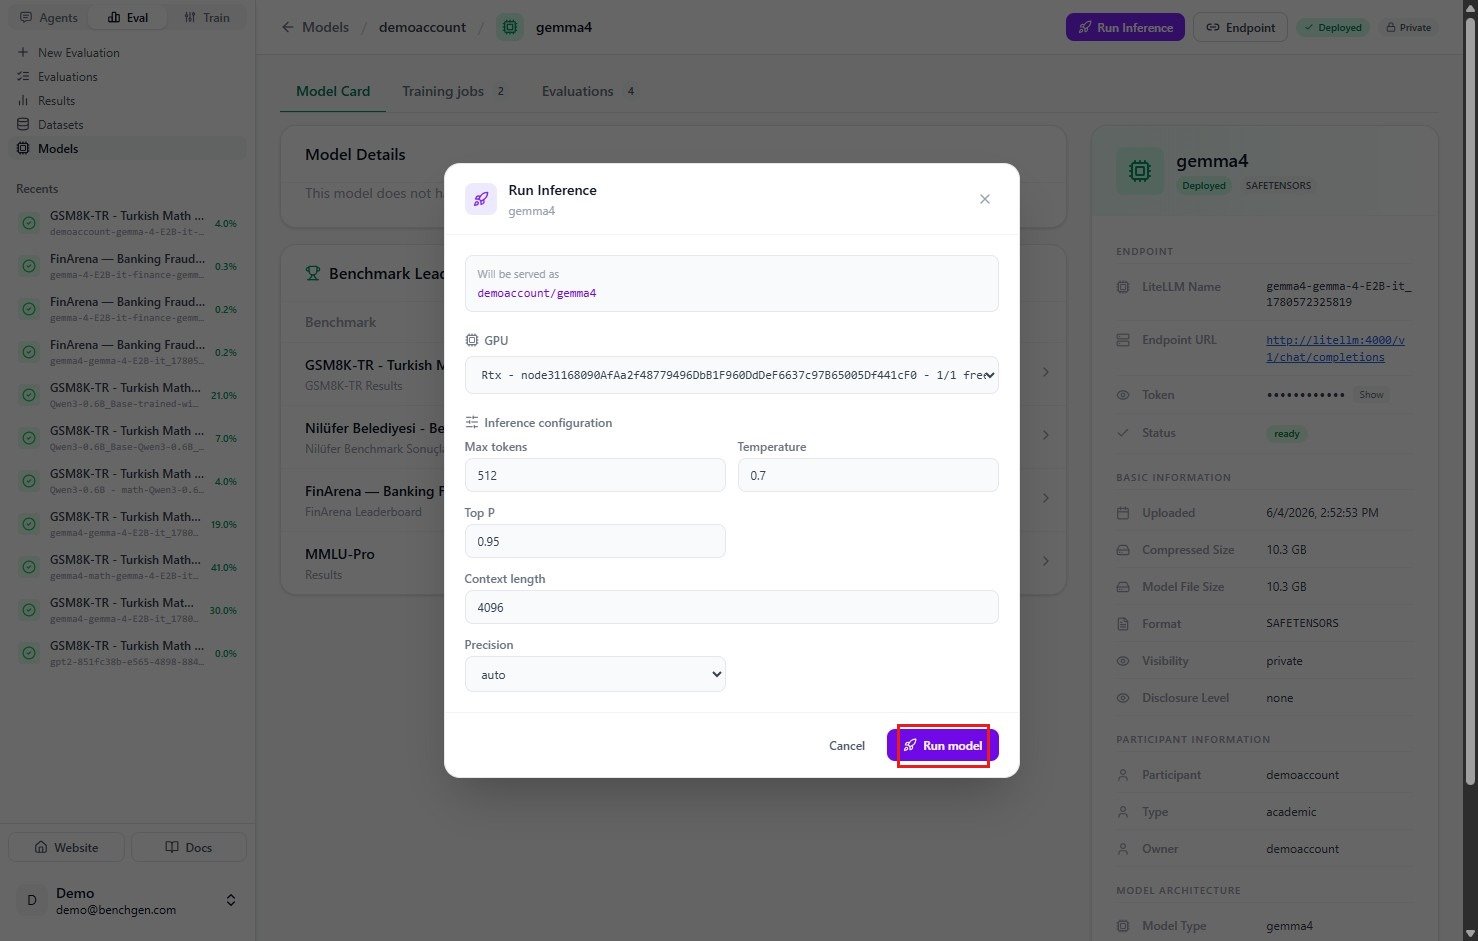
The Run Inference dialog with GPU selection and inference settings, Run model outlined
3. Wait for the endpoint to be ready
The status reads Deploying while the model starts up, then turns to running once it’s live. The model card’s endpoint panel fills in with the model’s identifier, Endpoint URL, and access token.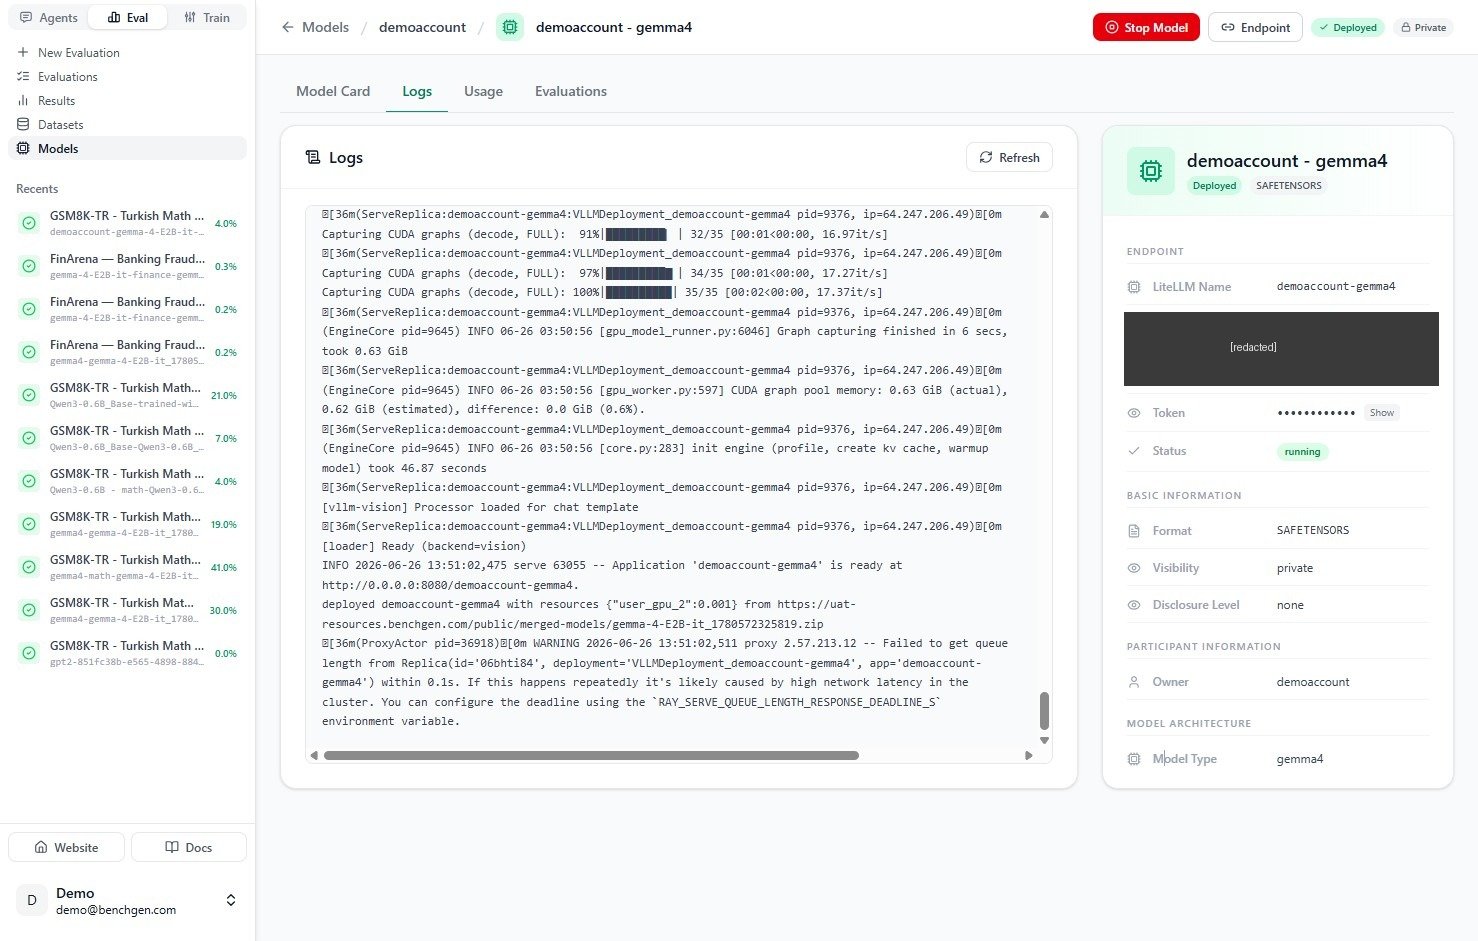
Logs showing the application is ready and the status set to running
Send requests
Once the status is running, the endpoint is OpenAI-compatible. Use the Endpoint URL, Token, and model name from the model card:Next Steps
Monitor Model Usage
Track requests, tokens, latency, and spend for this endpoint.
Evaluate an Inference Model
Benchmark it against an environment and watch the run in real time.
On a Platform Model
Run a formal benchmark to measure improvement.